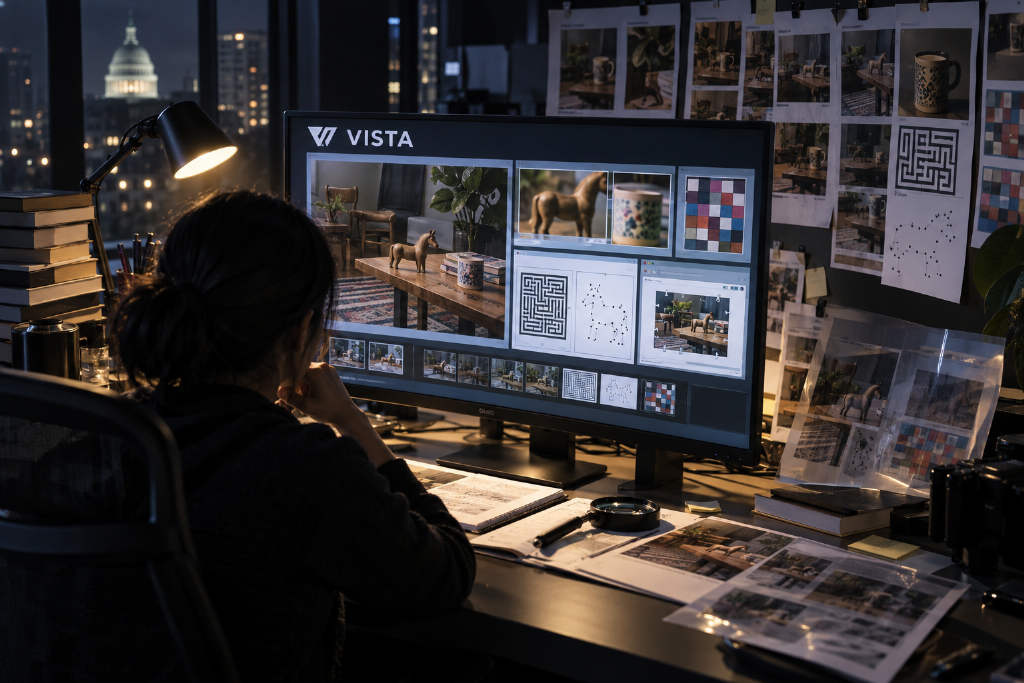
Kaiming He2026-10-09 07:58:55Kaiming He’s team introduces VISTA, a visual harness that lets multimodal models revisit past observationsA team led by MIT professor Kaiming He has introduced VISTA, short for "A Visual Harness for Reasoning in an Interactive World," a framework designed to help existing multimodal models preserve and reuse visual experience during long interactive tasks. Instead of converting an environment into text or code and relying on summaries, VISTA stores raw visual frames outside the context window and lets the model pull them back when needed for inspection, comparison, zooming, and pixel-level checks. The paper reports strong results on ARC-AGI-3, an interactive visual reasoning benchmark where rules and goals are not given in advance. With VISTA, Claude Opus 5.0 completed all 25 public games, achieved a relative human action-efficiency score of 100, and used 57.4% fewer game actions than the first-play human baseline. GPT-5.6 Sol also cleared all 25 games and scored 99. The framework is built around three parts: visual observation, lossless visual memory, and active visual inspection. It also uses two text notes, GUIDE.md and WORKING.md, to preserve reusable rules and current task progress across context windows. Beyond ARC-AGI-3, the team tested VISTA on GameWorld, AI GameStore, and BabyVision, reporting gains in browser games, mazes, and connection puzzles. The authors say future validation should move toward embodied tasks in environments that more closely resemble the physical world.10
Elorian2026-07-18 10:44:30Visual reasoning AI startup Elorian raises $55 million seed round at a $300 million post-money valuationU.S.-based visual reasoning AI startup Elorian has raised $55 million in a seed round, reaching a $300 million post-money valuation, according to BlockBeats. The valuation stands out because the company has not yet released a product. The round was co-led by Striker Ventures, Menlo Ventures and Altimeter Capital, with participation from Nvidia and Google senior vice president Jeff Dean. Elorian formally emerged from stealth in April 2026. The company is led by two co-founders with major AI backgrounds: Andrew Dai, who spent 14 years at Google DeepMind and worked on early large language model research that later informed ChatGPT development, and Yinfei Yang, who previously led work on multimodal AI systems at Apple. The startup has also assembled a core team drawn from leading AI labs around the world, covering pretraining, data and multimodal AI. BlockBeats said Elorian’s $300 million post-money valuation is roughly 20 to 60 times the traditional pre-seed valuation range of $5 million to $15 million, highlighting the premium institutional capital is placing on founders with advanced AI research pedigrees.1890